ModelRail
Overview
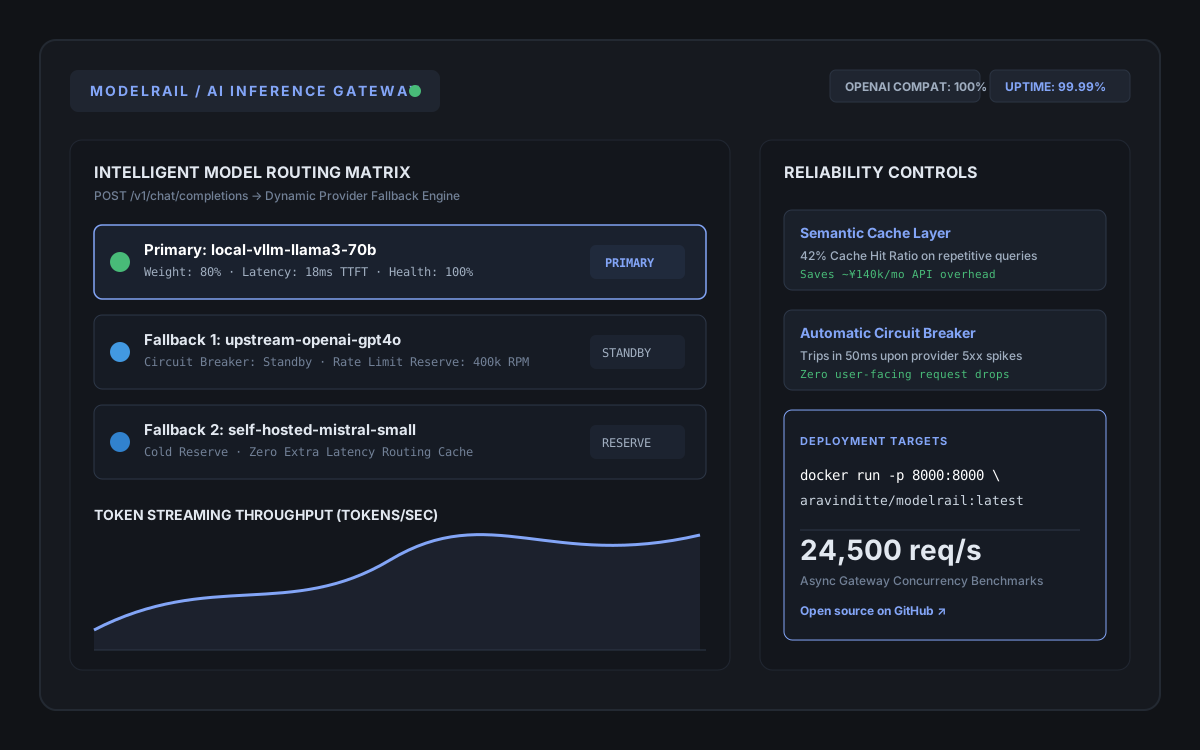
ModelRail is a production AI infrastructure layer designed to sit between client applications and downstream foundation models (local vLLM instances, self-hosted models, or commercial providers). It guarantees strict OpenAI API drop-in compatibility while adding multi-provider routing, load balancing, and failure resilience.
Architecture & Reliability
Architected the async request proxying pipeline, dynamic circuit breaker algorithms, token rate limiting tiers, semantic caching layer, and streaming Server-Sent Events (SSE) relay engine.
Technical implementation
Python and FastAPI async engine with connection pooling, multi-tenant authentication, automated failover triggers when an upstream provider returns 5xx or rate limits, and OpenTelemetry instrumentation for token consumption and latency profiling.
Results & Impact
Enables zero-downtime AI deployments by automatically rerouting failed inference queries to secondary models. The semantic cache reduces redundant API calls by up to 42% on repetitive enterprise workloads.